fact_checkResearch-based first look
Table of ContentsOpenClose
- Fireworks AI at a glance
- What Fireworks AI is designed to do
- The part I like most
- Core features and buyer value
- The catch
- Fireworks AI pricing in 2026
- Who should use Fireworks AI?
- How I would test Fireworks AI
- Fireworks AI alternatives
- Related reading for this decision
- My final verdict
- Frequently asked questions
Fireworks AI at a glance
| Question | Answer |
|---|
| What is it? | generative AI inference, fine-tuning and model infrastructure platform |
| Best for | AI engineering teams deploying open-weight or fine-tuned text and multimodal models into latency-sensitive products |
| Less suitable for | non-technical buyers seeking a finished business application or teams committed exclusively to one proprietary model API |
| Pricing | Sales-led unless stated otherwise below |
| Review access | Public-evidence first look; no authenticated workspace |
| Main buying test | Prove accurate, governed outcomes on representative work |
What Fireworks AI is designed to do
The product is designed around five buyer jobs:
- Access open models through serverless APIs
- Deploy dedicated on-demand or reserved model capacity
- Fine-tune and adapt models for specific tasks
- Serve text, image, audio and multimodal workloads
- Optimise latency, throughput and cost at production scale
The part I like most
The choice of inference deployment models is useful when the workload changes from experimentation to sustained traffic.
- Multiple deployment modes from serverless to reserved capacity
- Visible model-level token pricing
- Optimised infrastructure targets latency and throughput
- Supports inference, fine-tuning and several modalities
Core features and buyer value
Serverless inference
Fireworks charges per token across a changing catalogue and provides OpenAI-compatible interfaces. Test tool use, structured output, streaming, context handling and overload behaviour for the exact model.
On-demand and reserved deployments
Dedicated GPU deployments offer control and predictable capacity, while reserved arrangements target sustained scale. Compare utilisation and queueing against serverless before committing capacity.
Inference optimisation
Fireworks promotes an optimised disaggregated engine, caching and model-specific performance. Measure time to first token, output throughput, p95/p99 latency and errors over realistic prompt lengths.
Fine-tuning and training
Fine-tuning can improve specialised quality but adds dataset, evaluation and model-lifecycle work. Maintain holdout tests and compare the tuned model with prompting and retrieval baselines.
Multimodal model catalogue
Text, image, audio, vision and embedding models can reduce provider fragmentation. Model updates and data terms may differ, so each endpoint needs a recorded approval and fallback.
The catch
I would not assume a provider benchmark describes my tail latency, model quality or failover behaviour.
- Prices and model availability can change rapidly
- Provider speed claims need workload-specific benchmarking
- Fine-tuned models increase governance and migration cost
- Inference concentration requires fallback planning
Fireworks AI pricing in 2026
Pricing evidence was recorded on 20 July 2026. The figures and plan descriptions below are historical research, not a newly verified quote. Confirm current terms with Fireworks AI before budgeting.
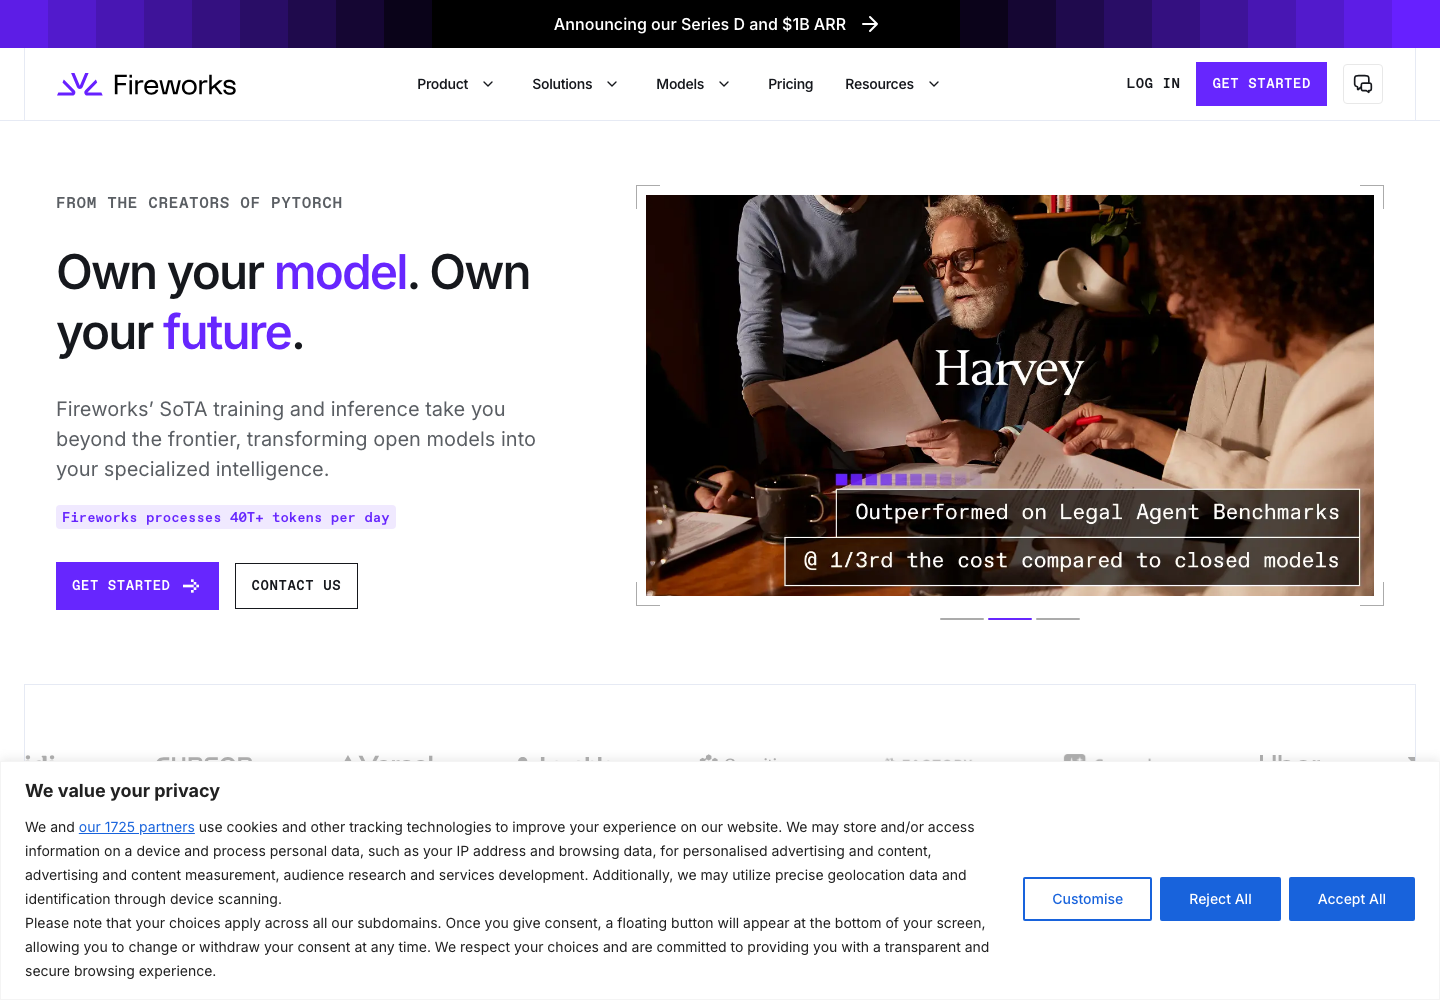
Fireworks uses pay-as-you-go per-token pricing for serverless inference, per-GPU time for on-demand deployments and training-data usage for fine-tuning. Rates differ by model; for example, the homepage listed OpenAI gpt-oss-20b at $0.07 per million input tokens and $0.30 output when checked. New users receive credits, while Enterprise terms are custom.
Who should use Fireworks AI?
Fireworks AI is best suited to AI engineering teams deploying open-weight or fine-tuned text and multimodal models into latency-sensitive products.
It is less suitable for non-technical buyers seeking a finished business application or teams committed exclusively to one proprietary model API.
How I would test Fireworks AI
For Fireworks AI, my proposed test would use this scenario rather than begin with a production rollout:
An AI team replays a representative production trace against two Fireworks models and its incumbent provider. It measures quality, safety, latency, token use, caching and errors, then sends a small percentage of live traffic with automatic fallback and cost alerts.
Fireworks AI alternatives
| Alternative | Consider it when |
|---|
| DeepInfra | Low-cost broad model access is the main comparison |
| Together AI | Open-model inference, training and research ecosystem matter |
| GroqCloud | Extreme token generation speed on a narrower catalogue leads |
| AWS Bedrock | Cloud governance and multiple managed model providers are required |
| Self-hosted vLLM | Control and sustained utilisation justify operating GPUs |
Before adding Fireworks AI to a shortlist, I would write down the job, the current alternative and the evidence needed to justify a change. Our guide to a requirements-first approach to choosing AI tools.
For Fireworks AI, I would also count the existing tools, review time and operating work that remain after adoption. Our guide to a framework for reviewing overlapping software costs.
I would use the AI Tool Chooser to organise the shortlist around requirements before a vendor discussion. It does not replace the product-specific, technical or professional validation described for Fireworks AI.
For related inference buying decisions, I would also read our DeepInfra review and Mistral AI review. These are adjacent evaluations, not a claim that every product replaces Fireworks AI.
My final verdict
I would put Fireworks AI on a conditional shortlist for AI engineering teams deploying open-weight or fine-tuned text and multimodal models into latency-sensitive products.
I would not assume a provider benchmark describes my tail latency, model quality or failover behaviour.
Frequently asked questions
How does Fireworks AI charge?
Serverless is generally billed per token, on-demand deployments by GPU time and fine-tuning by training usage.
Does Fireworks offer free credits?
Its documentation says new users automatically receive free credits.
Is Fireworks AI an application?
No. It is infrastructure and APIs for teams building generative AI products.
Was this Fireworks AI review hands-on?
No. It is a research-based first look using official public evidence. No authenticated workspace or production integration was tested.
Did Fireworks AI pay for inclusion?
No commercial relationship was disclosed for this review, and no rating was assigned.
Tolu S.
Operations Lead, AI Search & GEO
Leads operations for AI search visibility and generative engine optimization (GEO) campaigns.